
(Romy) Mi LUO
Hi there 👋! I am a final-year PhD student at UT Austin, co-advised by Prof. Kristen Grauman and Prof. Alex Dimakis.
I am currently a Student Researcher at Google DeepMind, working closely with Xuezhi Wang, Lijun Yu, Canoee Liu, and Adams Yu. Previously, I interned at Google, where I was fortunate to work with Du Tran, Wen-Sheng Chu, and Yujia Chen. Before joining UT Austin, I worked with Jiashi Feng at the National University of Singapore.
My research focuses on building multimodal generalist AI systems that understand, generate, and reason about the world they act in, from the digital to the physical, with broader interests in vision language models, multimodal agents and world models. [read more]
News
- [Nov. 2026]Check out our recent work on personalized visual context learning 📄.
- [Sep. 2026]Two papers accepted to NeurIPS 2026: AnchorSim and VIOS 🎉. See you in Sydney 🇦🇺!
- [Jul. 2026]LDO is accepted to ECCV 2026 🎉. See you in Malmö 🇸🇪!
- [May 2026]Started as a Student Researcher at Google DeepMind in Mountain View .
- [May 2026]Received the ICML 2026 Silver Reviewer Award 🥈.
- [Sep. 2025]Two papers accepted to NeurIPS 2025: Video-VER and AoT 🎉. See you in San Diego 🌴!
- [May 2025]Started as a Student Researcher at Google in Mountain View .
- [Feb. 2025]ViewpointRosetta is accepted to CVPR 2025 as an Oral 🎉. See you in Nashville 🎸!
- [Sep. 2024]Two papers accepted to NeurIPS 2024: HOI-Swap and EnsV 🎉. See you in Vancouver 🍁!
- [Jul. 2024]Two papers accepted to ECCV 2024: 4DIFF and Exo2Ego 🎉. See you in Milan 🇮🇹!
- [May 2024]Started a research internship at FAIR, Meta AI in Menlo Park .
- [Feb. 2024]Ego-Exo4D is accepted to CVPR 2024 as an Oral 🎉. See you in Seattle 🏔️!
 .
 .
 .
Research Interests
My research builds multimodal generalist AI systems that cross from the digital world into the physical world. I work on the learning signals and data that let multimodal LLMs ground their reasoning in verifiable evidence, acquire skill from existing human demonstrations, and represent the state of the world they act in. Specifically:
-
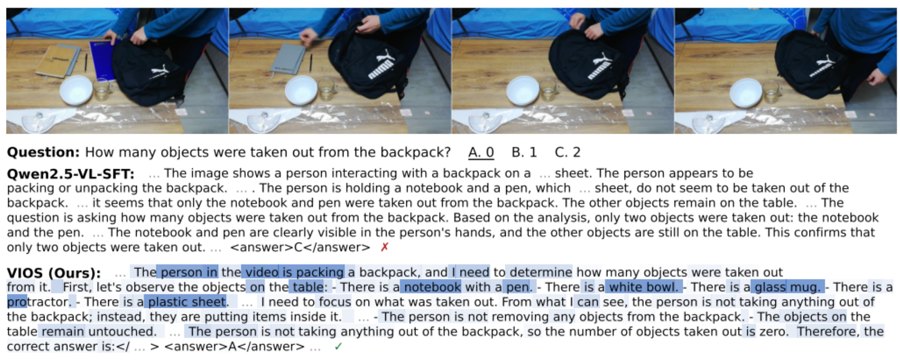
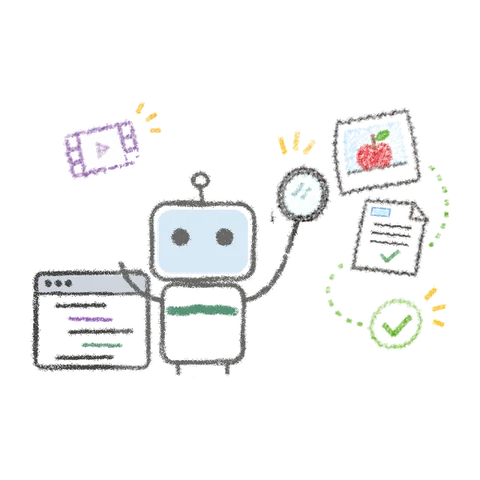 Digital Agents → Verifiable Reasoning. I am interested in agents that reason over image, video, language, and interface without drifting from what is actually there. My work develops verifiable rewards, self-auditing, and long-term memory so that reasoning stays anchored in visual evidence and personalized to the user.
-
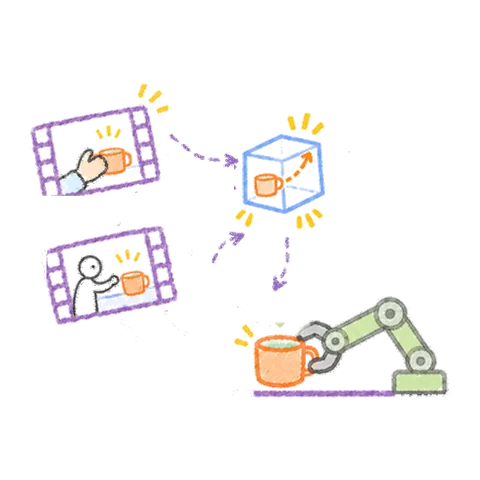 Human Video → Transferable Skill. I am interested in turning human video, especially egocentric data, into scalable training data for generalist agents. My work explores how paired and unpaired first-person and third-person web video, multimodal human demonstrations, and 3D geometry enable knowledge transfer across viewpoints, from watching someone else act to the first-person view an agent would have itself.
-
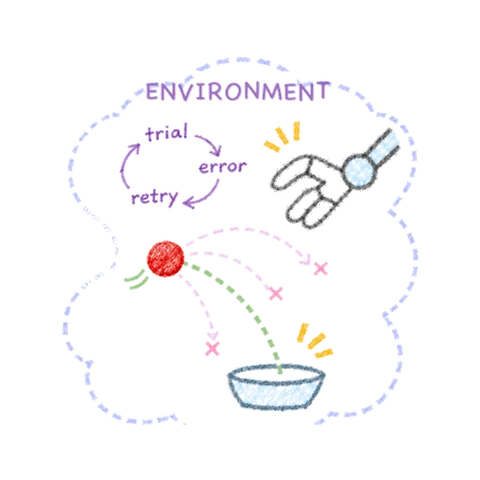 World Models → Physical Intelligence. I am interested in world models in two roles: as interactive environments an agent can act in, learn from, and co-evolve with, and as a representation of world state, especially causality and physics. My work tests whether today's frontier video models actually hold that state. Largely they do not. I think the missing piece is latent state: a model has to recover what is actually in a scene before it can predict what follows, which is why structured representations of that state matter.
Publications & Manuscripts
My work falls into three threads: 🧠 multimodal reasoning & agents, 🎬 video world models & multimodal generation, and ⚙️ model architecture, optimization & reliability. In total, these projects cover multimodal data, post-training / RL rewards, and evaluation / benchmarks.
🧠 Multimodal Reasoning & Agents
Data, RL / Verifiable Rewards, Evaluation, Personalization


-

Ego-Exo4D: Understanding Skilled Human Activity from First-and Third-Person Perspectives Kristen Grauman, Andrew Westbury, Lorenzo Torresani, Kris Kitani, Jitendra Malik, …, Mi Luo, …, Pablo Arbelaez, Gedas Bertasius, David Crandall, Dima Damen, Jakob Engel, Giovanni Maria Farinella, Antonino Furnari, Bernard Ghanem, Judy Hoffman, C. V. Jawahar, Richard Newcombe, Hyun Soo Park, James M. Rehg, Yoichi Sato, Manolis Savva, Jianbo Shi, Mike Zheng Shou, Michael Wray
In IEEE/CVF Conference on Computer Vision and Pattern Recognition, CVPR 2024. (Oral, EgoVis Distinguished Paper Award)
[PDF][Project][Blog][Video]


🎬 Video World Models & Multimodal Generation
Generative Modeling, Training Signals, Evaluation


⚙️ Model Architecture, Optimization & Reliability
Architecture, Optimization, Test-time Calibration, Model Selection
-

MetaFormer is Actually What You Need for Vision Weihao Yu, Mi Luo, Pan Zhou, Chenyang Si, Yichen Zhou, Xinchao Wang, Jiashi Feng, Shuicheng Yan
In IEEE/CVF Conference on Computer Vision and Pattern Recognition, CVPR 2022. (Oral)
[PDF][Project][Marktechpost News][QbitAI News (in Chinese)]


-

MetaFormer Baselines for Vision Weihao Yu, Chenyang Si, Pan Zhou, Mi Luo, Yichen Zhou, Jiashi Feng, Shuicheng Yan, Xinchao Wang
IEEE Transactions on Pattern Analysis and Machine Intelligence, T-PAMI 2023.
[PDF][Project][Synced News (in Chinese)]
-

Architecture Personalization in Resource-constrained Federated Learning Mi Luo, Fei Chen, Zhenguo Li, Jiashi Feng
In NFFL Workshop, NeurIPS 2021. (Selected as outstanding paper, acceptance rate: 9%)
[PDF]
-

MetaSelector: Meta-Learning for Recommendation with User-Level Adaptive Model Selection Mi Luo, Fei Chen, Pengxiang Cheng, Zhenhua Dong, Xiuqiang He, Jiashi Feng, Zhenguo Li
In Proceedings of The Web Conference, WWW 2020.
[PDF]
Research Experiences
- Google DeepMind
Student Researcher, Topics: Gemini-Omni, reasoning
 Google DeepMind
- Google
Student Researcher, Topics: video world models
 Google
- FAIR, Meta AI
Research Intern, Topics: video encoder and representation learning
 FAIR, Meta AI
- SEA AI Lab (SAIL)
Research Intern, Topic: vision transformer architecture
 SEA AI Lab (SAIL)
- National University of Singapore
Research Assistant, Topics: federated learning, machine learning with non-IID data
 National University of Singapore
Professional Service
- Conference Reviewer
- IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), since 2023
- European Conference on Computer Vision (ECCV), since 2024
- IEEE/CVF International Conference on Computer Vision (ICCV), since 2023
- Asian Conference on Computer Vision (ACCV), since 2024
- Conference on Neural Information Processing Systems (NeurIPS), since 2023
- International Conference on Learning Representations (ICLR), since 2024
- International Conference on Machine Learning (ICML), since 2024
- International Conference on Artificial Intelligence and Statistics (AISTATS), since 2022
- AAAI Conference on Artificial Intelligence (AAAI), since 2025
- Journal Reviewer
- International Journal of Computer Vision (IJCV)
- IEEE Transactions on Knowledge and Data Engineering (TKDE)
- Transactions on Machine Learning Research (TMLR)
- Teaching Assistant
- EE2211 Introduction to Machine Learning
- CG3207 Computer Architecture
Blog
-
The Flip Test: Video World Models Fail to Learn the World State
Video models are increasingly used as world models for robotics and planning. We test the assumption underneath: if a small change to a scene flips the real outcome, the prediction should flip too. Across 11 frontier models it mostly does not, while a coding agent given tools to measure the same images solves 93.3% of the pairs.


Built with 🧑💻 + AI 🤖 with ❤️
Typography adapted from the clarity template.